---
title: "The Bottleneck Wasn't the Hardware, Again"
subtitle: "Three times the machine looked like the problem: a night that produced nothing, a two-card speed-up that never arrived, and a box that froze in total silence. Three times we measured before we replaced anything — and the hardware was innocent every time."
date: 2026-08-27
events: "21.7.–2.8.2026"
tags: ["somnus"]
summary: "Hardware is the most satisfying suspect in computing: visible, blameable, replaceable. This part is three cases where it was the obvious answer and the wrong one — including a freeze we still cannot explain, and the repair we are deliberately not performing because it would destroy the evidence."
canonical: https://sf3d.fi/blog/the-bottleneck-wasnt-the-hardware-again
html: https://sf3d.fi/blog/the-bottleneck-wasnt-the-hardware-again
author: Petri Korhonen, SF3D AI Lab (Sunrise Software Oy, Tampere, Finland)
site: https://sf3d.fi (index of all articles in Markdown: https://sf3d.fi/llms.txt)
numbers: measured on the lab's own hardware unless the text marks them as held for the AMD R9700 whitepaper; the Evidence block at the end of an experimental article names the run, the date, n and the pre-registration each claim rests on
---
When a machine is slow, or stops, or just will not produce, the hardware is the first thing anyone reaches for. It is the most satisfying suspect in all of computing — you can see it, you can blame it, and best of all you can buy a new one. Three times this summer the hardware was the obvious answer. Three times we measured first. It was innocent every time, and the third case is still open: we do not know what stopped the machine, we know precisely what did not, and we are deliberately not doing the repair that would make the symptom go away.
## First: the night that produced nothing
The machine ran for eleven hours without interruption. Ninety-nine generation cycles, a hundred and seventy-eight screening passes, twelve rounds of synthesis. In the morning the count of new ideas it had produced was **zero**.
Not a crash. Not an error in the log. It had done all the work and there was nothing at the end of it.
The reflex here is memory. It is always memory. More RAM, a bigger model, another card — the machine is clearly straining, so give it more machine.
More RAM would have produced exactly as many ideas: none. The generator's job is to find *missing connections* between things the archive already believes. It was drawing on `236` verified items, which admit a finite number of meaningful pairs — `4,569` of them — and it had already proposed every single one. It kept a record of which pairs it had seen, so it dutifully skipped them all and wrote nothing. The machine was not straining. It had finished, and nobody had told it.
The fix cost nothing and involved no hardware. The archive holds more than its verified conclusions: it also holds untested hypotheses, and records of past sessions, and those live in the same mathematical space as the verified ones — the same coordinates, directly comparable. We let the sampler draw on those too. New candidates went from zero to `4,406`.
There is a footnote to that day worth keeping, because it is the same lesson pointed at ourselves. A dry run reported that only `18` of `343` stored hypotheses passed the filter, which looked like a catastrophe — most of the shelf apparently dead. Checked directly against the database, all of them were alive. The `18` was an artefact of the filter one of us had just written. The build diary falsified its own conclusion inside a day, which is roughly the rate we would like to keep.
## Second: two cards, one wrong assumption
The box has two GPUs. So when the next question was how to make the model generate faster, the architecture practically wrote the hypothesis for us.
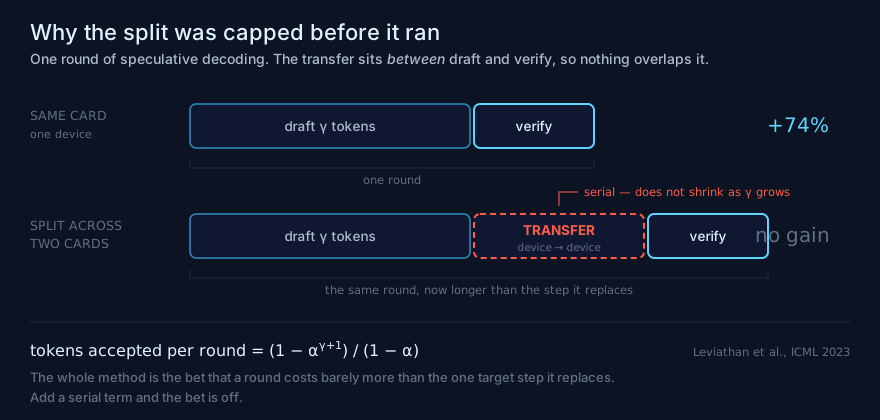
The technique is speculative decoding: a small, fast model guesses the next several tokens, and the large model checks the whole batch in one pass instead of producing them one at a time. Cheap guesses, expensive verification, done in bulk. It works — that part is not in doubt.
The tempting version was to split it across the two cards. Small model on one, large model on the other. Two cards, two jobs, parallel work. It is such a clean picture that not trying it would have felt like negligence.
The measurement took one afternoon and came back split cleanly in two:
- **Both models on the same card:** a large gain on code prompts (the ratio is held for the hardware paper). The technique delivers.
- **Split across the two cards: no gain.** The transfer across the bus between them, once per round, ate everything the trick had bought.
"Two cards means the work should be divided between two cards" is an intuition, not a result, and for this workload it was simply false. What made it cheap to find out was that we asked the machine instead of arguing about it.
And then the good part, which arrived out of the wreckage rather than the plan. While measuring the failed version we found a variant that needs no second model at all: the large model speculates against **its own recent output** — repeated phrasings, repeated identifiers, the ordinary redundancy of structured text — and verifies its guesses the same way. No draft model, no second card, no transfer.
We did not take that on faith either. It went into production and was measured in the field on real screening calls: `1.82×` faster, no quality change, no new component. The flag now sits on two live service units. (The throughput series itself belongs to the hardware paper; the blog gets the method.)
One trap from that deployment is worth publishing, because it is the kind that gets "fixed" by someone helpful. The first call after a server restart always reports no speculation and baseline speed, every time, because the pattern cache is empty and has nothing to guess from yet. That is correct behaviour that is indistinguishable from a broken feature. It is now written down, which is the only defence.
The transfer is not slow because the bus is slow. It is fatal because it is serial and sits inside the round — so proposing more tokens amortises it and never removes it.
## Third: the machine that stopped without saying anything
Twice in one morning the box froze. Not crashed — froze, in complete silence, after `87 minutes` the first time and `40` the second.
There was no kernel panic. No out-of-memory kill. No GPU fault, no machine-check exception, no disk error. Nothing reached the disk at all: the kernel's log simply stops, seventy minutes before the first freeze and forty before the second, and resumes at the next boot.
The ordinary version of this story ends "we replaced the motherboard and the problem went away." That ending is available to us and we are not taking it, for a reason worth stating plainly: **a swap that replaces the board, the processor, the memory and the disk in one operation cannot tell you which of them it was.** If the symptom disappears you have bought silence, not an answer, and you will believe a cause you never tested. We wrote that into the procedure *before* the parts were ordered, precisely so nobody could reason backwards from a happy outcome later.
So instead, each suspect was refuted individually.
**The bus.** Error counters on all four devices: zero, zero, zero. Both links negotiated at full width and full speed. Refuted.
**A memory leak.** Sixteen consecutive model loads and unloads. Memory returned each round — between `592` and `625 MB` back every cycle — and the kernel's own allocator grew by `3 MB` across all sixteen. Refuted.
**The disks.** Both drives pass, every failure counter at zero, one of them reporting `100%` of its life remaining. Refuted.
And then the good suspect, the one we expected to be right. A specific driver path was hogging the processor for over ten milliseconds at a time, its counter climbed with every model swap, and it had appeared seventy minutes before the first freeze. It runs on a shared work queue, so if it ever wedged there, everything behind it would stop — and stop *quietly*, with no panic, which matched the symptom exactly.
We drove that counter deliberately to `131` and the machine did not so much as stutter. Refuted, and it was the one we wanted.
What replaced the guessing was instrumentation. The kernel's last words now go out over the network to a remote server as they are written, so a freeze that never reaches the local disk still leaves a record somewhere else. We validated that channel with a real shutdown and watched the full sequence arrive intact — which is the step that turns it into an instrument rather than a hope. Because the channel is proven, **silence is now data**: if the machine stops and nothing at all comes out of a link we know works, the processor stopped in one piece, and that points at power or hardware rather than software.
One blind spot got smaller at a known price. The professional card supports error-correcting memory on the GPU, and it was switched on. The cost is exactly `2.000 GiB` of video memory (`31.860 → 29.859 GiB`, `6.28%`), with no measurable slowdown, and in exchange memory errors on that card are now visible instead of silent. The consumer card in the same box has no such capability, so that half of the machine stays dark.
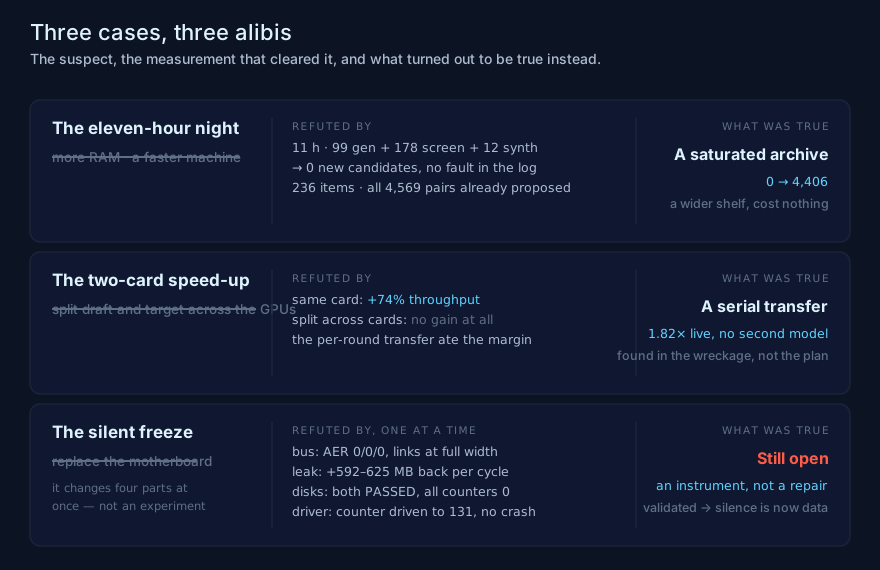
Three unrelated failures, one available mistake. The third row is the one worth staring at: every suspect cleared, and the case still open — which is the honest end of the story rather than a failure of it.
## What survives
The three cases have nothing technical in common. A saturated archive, a bus transfer, and a silent stop are unrelated failures in unrelated layers. What they share is the shape of the mistake that was available in each one:
1. **Hardware is the suspect that requires the least thought and offers the most action.** That combination is exactly why it should be the one you check with the most discipline, not the least.
2. **A hypothesis the architecture suggests is still just a hypothesis.** Two cards made the split version feel like the obvious design. One afternoon of measurement was cheaper than one week of building it properly first.
3. **The best result of the summer came out of a falsified hypothesis, not a confirmed one.** We would never have found the single-model variant if the two-card version had quietly half-worked. A clean negative sends you looking; an ambiguous positive keeps you tuning.
4. **A repair that changes four things at once is not an experiment, and its success is not evidence.** If you cannot resist making the symptom go away, at least write down beforehand that you will not be entitled to a conclusion.
5. **Validate the instrument, and silence becomes a measurement.** An untested logging channel that stays quiet tells you nothing at all. A tested one that stays quiet has told you where the fault is not.
The freeze has not recurred. We still do not know what it was, and the trap is set for the next one.
## Sources & further reading
- Y. Leviathan, M. Kalman & Y. Matias, *Fast Inference from Transformers via Speculative Decoding* (ICML, 2023) — the acceptance-rate/cost model the two-card analysis rests on.
- C. Chen et al., *Accelerating Large Language Model Decoding with Speculative Sampling* (2023) — the concurrent formulation, with the same round-cost structure.
- G.M. Amdahl, *Validity of the single processor approach to achieving large scale computing capabilities* (AFIPS, 1967) — why a serial term inside the accelerated loop bounds the whole result.
- J.R. Platt, *Strong Inference* (Science, 1964) — the discipline of refuting suspects one at a time rather than confirming a favourite.
- J. Gray, *Why Do Computers Stop and What Can Be Done About It?* (Tandem TR 85.7, 1985) — the classic taxonomy of silent and transient faults, and why the ones that leave no trace are their own category.
- J.L. Hennessy & D.A. Patterson, *Computer Architecture: A Quantitative Approach* — the standing argument that measurement precedes optimisation, in the form most engineers first met it.
---