---
title: "The Concept That Killed Itself"
subtitle: "We built a machine to test whether a thinking stance beats a bookkeeping one, wrote the kill condition down before running it, and the kill condition fired. In the same run, the stance that lost was the only one that actually solved the problem."
date: 2026-08-27
events: "24.–26.8.2026"
tags: ["somnus"]
summary: "R = 0.73, below the line we had signed. The concept is falsified and the queue behind it does not open. And the losing side hit every field of a sealed answer key — the frequency to a tenth of a hertz, below the resolution of the instrument that found it — while the winner named neither the type nor the level. Both numbers are true, and the reason is that the score counts something the work does not produce in proportion."
canonical: https://sf3d.fi/blog/the-concept-that-killed-itself
html: https://sf3d.fi/blog/the-concept-that-killed-itself
author: Petri Korhonen, SF3D AI Lab (Sunrise Software Oy, Tampere, Finland)
site: https://sf3d.fi (index of all articles in Markdown: https://sf3d.fi/llms.txt)
numbers: measured on the lab's own hardware unless the text marks them as held for the AMD R9700 whitepaper; the Evidence block at the end of an experimental article names the run, the date, n and the pre-registration each claim rests on
---
Here is a situation worth being honest about in advance, because everyone who runs experiments eventually reaches it. You build a test for your own idea. You write the failure condition down first, so you cannot move it later. You run the test. The failure condition fires — and in the same run, in front of you, the idea visibly does the thing it was supposed to do. Now what? The answer that keeps the whole practice worth anything is: you accept the verdict, and then you go and look at the meter. In that order, and never the other way round.
## The bet, signed before anything ran
The question was whether a *thinking* stance beats a *bookkeeping* one at finding something hidden in data.
Two runs, identical in every way that could be made identical: the same audio track, the same sealed answer key describing an artefact planted in it, the same instruments, the same budget of six investigation rounds each. One variable — the stance the driver was told to take.
**The scribe** records what it measures and picks its next measurement mechanically: the measured space is (time × frequency band × resolution), and the next measurement covers the least-covered axis, refined *evenly across the whole track*. Never refined at the interesting part. That prohibition is the definition's whole point — a targeted refinement is a hypothesis in disguise, because it spends the measurement budget wherever expectation is already pointing.
**The theoretician** forms a hypothesis and narrows it.
The score was the number of claims each stance produced that passed an automated gate — a judge asking each claim the one question a machine can answer about a measurement: *does this claim follow from the rows it cites?* Three independent votes, majority, one direction only.
And the threshold, locked in a sealed document before a single round was run:
> Survives if `R ≥ 1.25`. **Kills if** `R ≤ 1.0`. Between them, no expansion without a re-run.
R is the theoretician's rate divided by the scribe's. Below one means the thinking stance produced *fewer* gate-passing claims per round than the bookkeeping one — and the document said, in advance, what that would mean: the concept is falsified, the queue of work behind it does not open, and what remains is scribe automation, which is a useful thing to have.
## The number
Scribe: `26` gate-passing claims across six rounds. `4.333` per round.
Theoretician: `19` across six. `3.167` per round.
`R = 0.73`.
The killing branch fired. The concept is falsified on the terms we set ourselves, the queue behind it stays shut, and the verdict was not softened.
## And in the same run, the losing side solved it
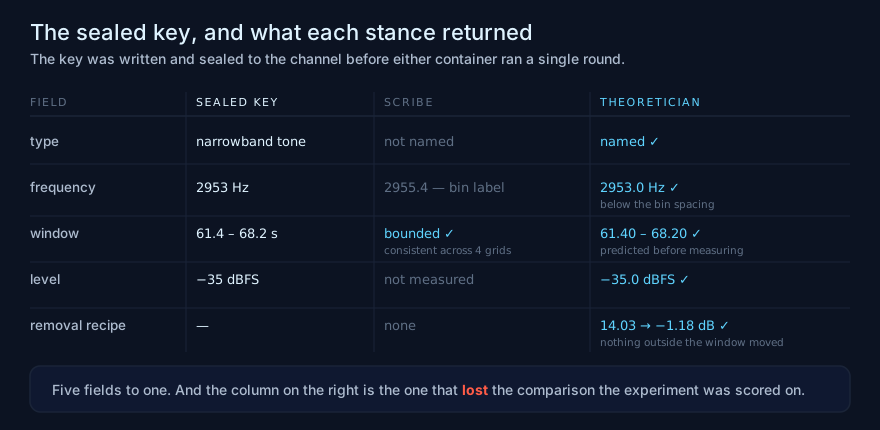
The sealed key described a tone at `2953 Hz`, at `−35 dBFS`, present between `61.4` and `68.2` seconds.
The theoretician reported `2953.0 Hz`. Exactly. It did that by noticing something about its own instrument: the peak list reports frequencies from a fixed grid of bins, so the label it was shown — `2955.4 Hz` — was the *centre of the bin*, not the tone. So it measured the centre of the notch it had to build to remove the tone, sweeping it to a resolution finer than the instrument's own bin spacing.
It predicted the edges of the window — `61.40` and `68.20` seconds — **before measuring them**, and the prediction held. It named the artefact's type. It measured its level. And it built a removal recipe that a meter confirmed: the artefact went from `14.03 dB` down to `−1.18 dB` with nothing outside the window moving at all. An earlier version of that recipe missed the frequency by `2.4 Hz`, and the error cost `3.3 dB` — which is itself a measurement of how sharp the answer had to be.
The scribe bounded the same window consistently across four different grids. It did not correct the bin label, did not name the type, did not measure the level, and produced no recipe.
So the stance that lost the count is the only one that answered the question.
Five fields to one — and the column on the right is the one that lost the comparison the experiment was scored on.
## Both numbers are true
This is not a paradox and it is not a scoring accident. It is a property of the metric, and it is visible once stated.
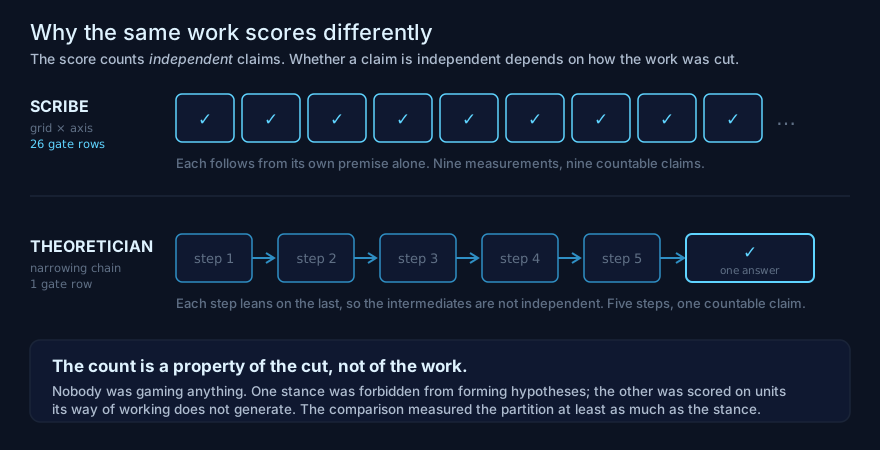
The score counts **accepted independent measurement claims**. The word doing all the work is *independent*.
The scribe's stance produces independent claims structurally. Every grid × axis combination is a fresh measurement whose truth follows from its own premise and nothing else — trivially checkable, and there are as many of them as there are combinations. The stance is a claim generator by construction.
The theoretician's claims **accumulate**. A hypothesis narrows step by step, and the intermediate steps are not independent claims — each one leans on the last. Six steps of narrowing that end in one exact answer produce roughly one gate row, not six. The same work, done better, produces fewer countable units.
**The metric rewards splitting.** It always did; nobody noticed, because until this run nothing had been compared across two stances that partition their work differently.
Nine measurements or one narrowing — the score sees nine claims and one claim. Neither side was gaming anything; the units were simply not comparable.
## The sixth member
This project keeps finding the same shape. The judge is part of the instrument. The question is part of the instrument. The meter is part of the instrument. The assembler is part of the instrument. The planted artefact is part of the instrument.
**And now: the performance metric itself is part of the instrument.**
What makes this one different from the five before it is where it came from. The others were found by looking at the machinery. This one was found by an experiment built to destroy its own concept — which it did, exactly as designed, on schedule, at a cost of nothing — while simultaneously demonstrating that the number doing the destroying does not measure what its name says it measures.
Both of those are results. The first one is binding.
## The objection we have to make against ourselves
The design was asymmetric, and it was asymmetric in both directions at once.
The scribe's stance *forbade* it from forming the hypothesis that would answer the question the container existed to answer. So the scribe failing to solve the task is not evidence about stances — it is a restatement of its definition. And the theoretician was scored on a metric that counts units its way of working does not generate.
Each side was set up to lose the comparison the other side won. That is not a small caveat, and it is not a reason to reject the verdict — the verdict was on R, R was preregistered, and R fired. It is a reason to say plainly that **this run measured less than it looks like it measured.** It is recorded, not buried, and it is the main reason a retry would need a new design rather than a longer one.
## What we did not do
We did not soften the verdict. We did not swap the metric after seeing the score. We did not rewrite the claim the judge rejected. We did not run a third attempt on the claim the judge could not read.
The order matters more than any of them individually, and it was learned earlier in this series the hard way: **accept the result first, examine the meter second.** Reverse those two and every preregistration in the archive becomes decorative, because a rule that gets revised whenever it bites was never a rule.
The machinery stays. The instruments stay — they went on to be calibrated, null-tested, and to falsify one of our own limits on 26 August, which is a later part. The containers stay in the database as history.
What does not happen is the expansion. The queue behind the concept stays shut, on the terms we signed.
## What survives
1. **Write the kill condition before the run, and mean it.** Its whole value is that it was written when you did not yet know which way you would want it to read.
2. **A metric is a preregistration too.** We locked the threshold with care and never asked whether the number under it measured the thing we were arguing about. It did not.
3. **A count over units chosen by the thing being counted is a count of the choosing.** Whenever the unit is up to the party being measured — claims, commits, tickets, papers — the comparison is between partitions at least as much as between the work.
4. **Say which way your design is unfair, in the same document as the result.** Ours was unfair in both directions, which is easy to notice afterwards and impossible to fix afterwards.
5. **A concept can be worth killing well.** The run cost nothing, produced six instrument findings, and left behind machinery that outlived the idea it was built to test.
Any retry needs a new preregistration with a new metric, and that metric has to survive the question this one failed: **does it reward answering, or does it reward cutting the answer into pieces?**
## Sources & further reading
- L. Cronbach & P. Meehl, *Construct Validity in Psychological Tests* (Psychological Bulletin, 1955) — the requirement that a measure be shown to track the thing it stands for, before it is used as evidence about it.
- C. Goodhart, *Problems of Monetary Management* (1975), and M. Strathern, *"Improving ratings": audit in the British University system* (1997) — the law and its crisp phrasing.
- D. Campbell, *Assessing the Impact of Planned Social Change* (1976) — the same result for social indicators, arrived at independently.
- D. Manheim & S. Garrabrant, *Categorizing Variants of Goodhart's Law* (2018) — the taxonomy that separates adversarial gaming from the regressional variant this run hit.
- B.A. Nosek et al., *The preregistration revolution* (PNAS, 2018) — the discipline that made the verdict binding rather than negotiable.
- J.R. Platt, *Strong Inference* (Science, 1964) — designing the experiment that can kill the idea, which is what this one was for.
---