---
title: "The Question Is Part of the Instrument"
subtitle: "A paid run aimed at exactly the right target produced content and zero structure; the same target, asked differently, overturned its own island. Four question forms later, the pattern was undeniable: the shape of the ask decides what kind of truth can come back."
date: 2026-08-22
events: "13.–22.8.2026"
tags: ["somnus"]
summary: "Part 4 ended with 136 forced pairs and no edges: aiming at the right target was not enough. This part puts the question itself under the microscope — four forms, four preregistered runs, locked answer keys, and a chain that named a theorem our own key did not contain. The question turns out to be an instrument component, and preregistration is the only reason any of it was visible."
canonical: https://sf3d.fi/blog/the-question-is-part-of-the-instrument
html: https://sf3d.fi/blog/the-question-is-part-of-the-instrument
author: Petri Korhonen, SF3D AI Lab (Sunrise Software Oy, Tampere, Finland)
site: https://sf3d.fi (index of all articles in Markdown: https://sf3d.fi/llms.txt)
numbers: measured on the lab's own hardware unless the text marks them as held for the AMD R9700 whitepaper; the Evidence block at the end of an experimental article names the run, the date, n and the pre-registration each claim rests on
---
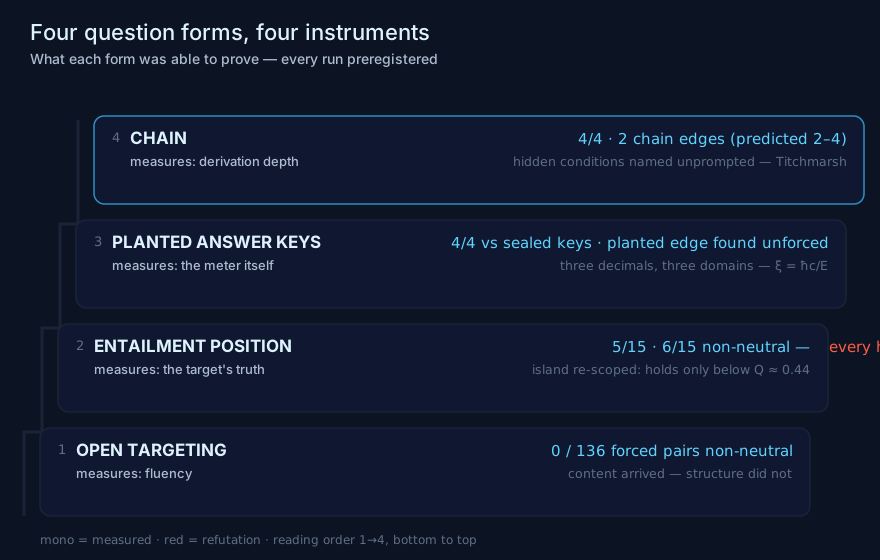
Part 4 closed on a puzzle. The corpus had been mapped — an archipelago, seventeen islands — and the obvious move, growing the strongest island by aiming an expensive run directly at it, produced new material and zero connections: 136 forced pairs, no edges. The aim was right. The machinery was validated. Something else was deciding whether new knowledge could attach to old. This part is about finding that something: it was the question. Not its topic — its form. Over four preregistered runs, the form of the ask went from suspect to measured instrument component: the judge is part of the instrument, and so is the question you hand it.
## A zero that survived good aim
The failed targeting run deserves its one paragraph, because its zero was unusually clean. The map said where to aim: next to the corpus's strongest mechanism island. The run was aimed there. Content arrived — new verified claims, on topic. And to rule out the soft excuse that the sampler simply never proposed the right pairs, every combination of new claim and island member was judged, all `136` of them, by force. Zero non-neutral verdicts. Not thin structure — none.
That leaves three suspects: the model cannot see consequence structure, the material cannot carry it, or the question cannot elicit it. The question in use was the pipeline's native open form — *here are two claims, what connects them?* — a form that invites an essay. Essays had been arriving. Essays do not commit to anything an entailment judge can grade.
## Ask for consequences, get a refutation
The next run kept everything fixed — same target island, same budget class — and changed only the question's form: it was rewritten into *entailment position*, phrased so that its answer must stand in a consequence relation to existing claims, gradable as `follows` / `contradicts` / `neutral`, rather than sit beside them as commentary.
The difference was not subtle. Zero non-neutral verdicts out of `136` became five from one judge, six from the other, out of fifteen. The form was the cause.
But the result betrayed the expectation in the most instructive direction available: **every hit was a contradiction.** The new claims did not extend the island; they measured it and found its core claim wrong. The island's anchor — a dramatic `~180°` phase anomaly at `20 Hz` — turned out to hold only below `Q ≈ 0.44`, and the realistic filter the claim was about runs near `Q ≈ 15`. (Part 4 promised that one of the islands would prove wrong in an instructive way. This is the island, and this is the way.) The decision rule for the run, locked in advance, technically fired — "at least five non-neutral verdicts" — but its silent assumption, that non-neutral would mean *consequence*, failed. The preregistered question itself had said, in writing, that falsification was part of the task — and the decision rule still did not know how to expect it. And structure did grow: next to the target, not into it. New edges formed among the new claims themselves, attached to what was true.
The question that asked for consequences produced a falsification — because the target was wrong, and the form finally gave the archive permission to say so.
The same run also produced a finding we told in Part 3: a `17×` throughput anomaly, visible only because the baseline had been written down before the run, exposed that two different judges had been silently in use. One preregistered number, two discoveries — one about the corpus, one about the instrument.
## Plant the answer before you ask
The refutation left a confound standing. If entailment-positioned questions yield contradictions and no consequences, is that because the *material* has no consequence structure to find — or because the *meter* cannot see consequences at all? Production data cannot answer that, because in production nobody knows the right answer.
So the next run planted it. Two questions were brought in from outside the process, chosen so their edge structure was known in advance. One was a dispersion-relation question whose consequence fan certainly exists — textbook physics, derivable step by step. The other was a premise whose correct outcome is a *quantified refutation*: a composite-electron model that real collider limits rule out by orders of magnitude. For both, answer keys were written and locked **before** the run — because in hindsight, every hallucinated number looks correct.
The machinery passed its exam. The planted positive edge — a core claim and its algebraic consequence, no new parameters needed — was judged correctly by both judges, and the pool screen surfaced it independently, without being forced. The answer keys hit `4/4`. Three derived numbers were checked by hand and came back correct to three decimals — `7.28 mm`, `5.06 eV`, `1.4139 fm` — all three from the same one-line formula, ξ = ħc/E, in three different domains of physics. The falsification side refused the composite model with numbers, not adjectives: the model's own logic demands new physics at `582–751 GeV`, and the collider record requires anything of the kind to sit above `12.9 TeV`. And the run's best surprise was logged as a *miss* against our own prediction: one claim came back sharper than the answer key it was graded against, deriving a bound our key did not contain.
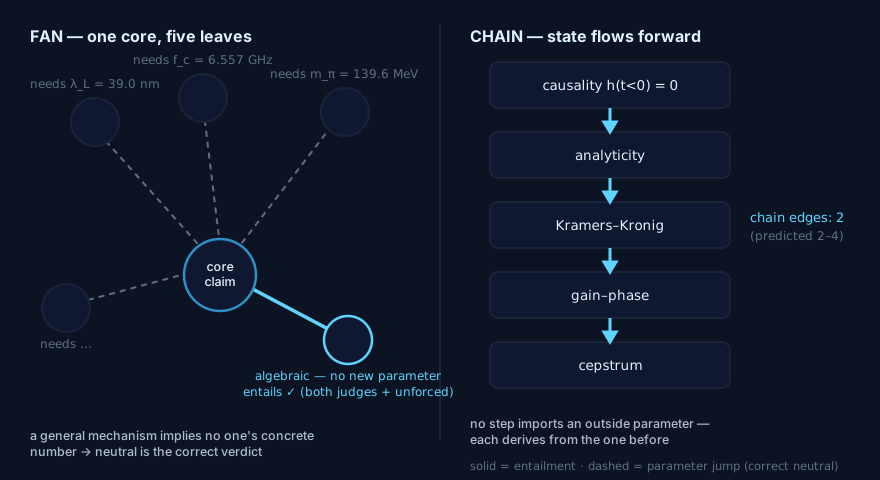
So that null was the substrate's property after all, not the meter's. The meter can see consequences — when they exist. And the run explained *structurally* why the fan question had produced only one edge: every other leaf of the consequence fan imports a parameter the core does not supply — a penetration depth, a cutoff frequency, a pion mass. A general mechanism does not imply anyone's concrete number. For those pairs, `neutral` is not a failure verdict; it is the *correct* verdict, and a system that returned anything else would be fabricating.
## Ask in a chain, not a fan
The fan diagnosis pointed directly at the fourth form. If fan leaves fail because each needs an outside parameter, then remove the outside: ask in a **chain**, where every step derives from the previous one and no step imports anything new. The next run did exactly that — a five-step causality chain, from time-domain causality through analyticity to dispersion relations, each link a consequence of the last.
The machine led the whole chain, `4/4` against the locked key. Chain edges landed at two, inside the predicted two-to-four. And the machine **named the hidden conditions of the derivation unprompted** — including Titchmarsh's theorem, the precise mathematical hinge between causality and analyticity, which our own answer key did not contain. The instrument, asked in the right shape, was sharper than its examiners. (The chain's edges, like the field edges before them, were visible only to the thinking judge — the judge-conditionality story of Part 3, holding at every scale.)
There is a coda the chain earned on its own. It left three real conflicts on the table — one between a new claim and the archive, confirmed in both directions; one between two of its own claims; and one that had waited in the queue since an earlier run, which the same machinery finally cleared — and resolving them became the corpus's first act of self-correction: eight claims came out *sharper*, and none came out dead. The falsification machine, in its first live test on its own memory, turned out to be a precision machine. That story, and what it forced us to build, is a later part.
Four forms, four instruments. Each rung changes what the answer is able to prove — from fluency, to the target's truth, to the meter's validity, to derivation depth.Why the fan stays neutral and the chain connects: a general mechanism implies no one's concrete number, so every parameter jump is a correct neutral. A chain carries its own state forward.
## The ladder
Read as one experiment, the arc measured four question forms and found they are four different instruments:
- **Open targeting** measures fluency. It will always produce something; what it produces cannot be graded.
- **Entailment position** measures the target's truth. It is the first form that can say *no* — expect it to say no to your favourite island.
- **Planted answer keys** measure the meter itself. A sealed key costs nothing to write — and it is the difference between "the material is thin" and "the judge is blind".
- **A chain** measures derivation depth — and outrunning the examiner becomes gradable, because every extra claim must still derive from the one before.
None of this was visible in the runs' headline outputs. It was visible in the gaps between locked predictions and outcomes: a baseline written before a run turned a speed-up into an instrument bug; a sealed key turned "the AI did physics" into a checkable claim; a decision rule that fired *correctly and misleadingly* exposed exactly which assumption had never been written down. Preregistration is not paperwork here. It is the difference between having results and having anecdotes.
What survives this part:
1. **A question form is an instrument setting.** It decides what epistemic act the answer can perform — essay, verdict, derivation — before any model quality enters the picture.
2. **Lock the key before the run.** Hindsight bends every number toward correctness.
3. **Preregister the decision rule's assumptions, not just its threshold.** A rule can fire exactly as written and still mislead through what it silently expected.
4. **When a fan yields neutrals, check for parameter jumps before blaming the model.** `neutral` is sometimes the only honest verdict — a system that never says it is fabricating.
The next experiments put the fourth form to work on fresh ground — a spectral-representation chain pointed at two islands at once — and the corpus's first self-correction has its own story to tell.
## Sources & further reading
- J.R. Platt, *Strong Inference* (Science, 1964) — the classic argument that the form of the question, not the effort behind it, sets the rate of progress.
- D. Mayo, *Statistical Inference as Severe Testing* (2018) — a claim is credited only by a test it could have failed; the lens behind the entailment-position form.
- B.A. Nosek et al., *The preregistration revolution* (PNAS, 2018) — the register-before-you-run discipline used in every run of this arc.
- E.C. Titchmarsh, *Introduction to the Theory of Fourier Integrals* (1937) — the theorem the machine cited unprompted.
- C.D. Chambers & L. Tzavella, *The past, present and future of Registered Reports* (Nature Human Behaviour, 2022) — locking the analysis plan before the data exists.
- J.S. Toll, *Causality and the dispersion relation: logical foundations* (Physical Review, 1956) — the physics the planted and chained questions were drawn from.
---